NeurIPS 2021 · 2021
Object-Centric Representation Learning with Generative Spatial-Temporal Factorization
When both the observer and the objects move, changes in an image have several possible causes. The Dynamics-aware Multi-Object Network (DyMON) extends multi-view object-centric learning to this setting, learning to separate camera motion from scene dynamics without object-level supervision.
Multi-view and dynamic scenes
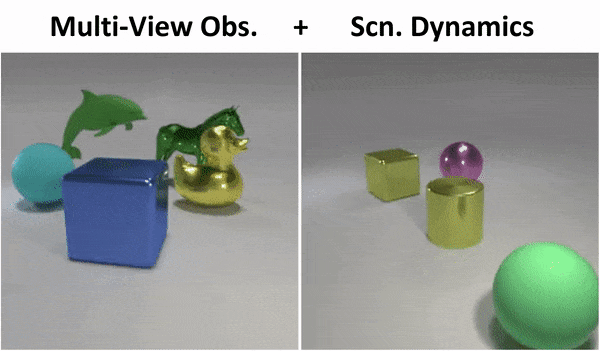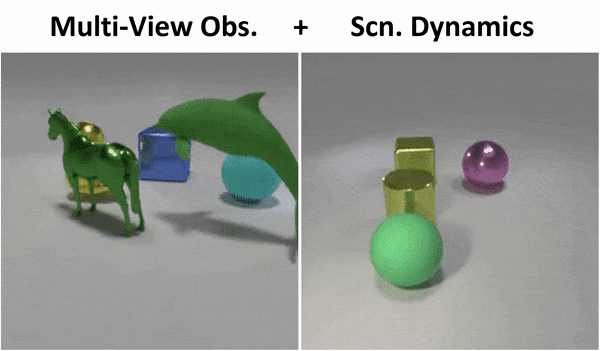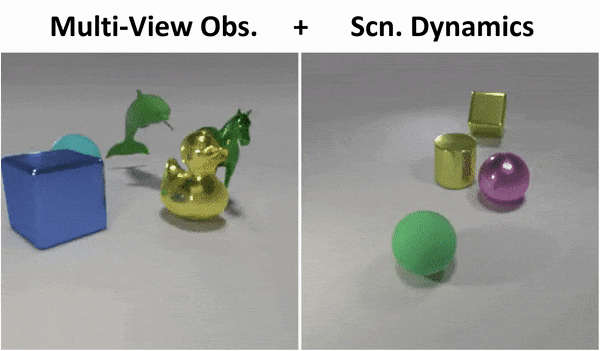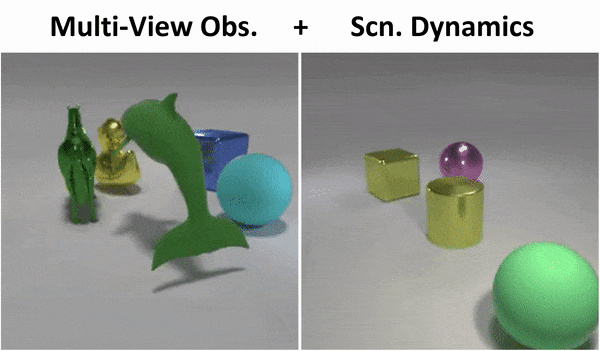

Querying objects in space and time
Methods that assume a fixed observer or a static scene cannot fully explain these combined changes. DyMON uses sequences of multi-view observations to factorize the effects of viewpoint and object dynamics, constructing spatial representations of individual objects as the scene evolves.
The resulting representation supports rendering a scene at queried times and viewpoints. Its object-wise factorization also allows individual objects to be queried independently across space and time, connecting unsupervised scene understanding with controllable generative prediction.
The CLEVR-Object-Centric repository provides the static and dynamic scene generators used for this line of work.